

Discover inefficiencies and quantify savings opportunities in your data platform


Optimizing Databricks Serverless for Cost and Performance
Thursday, November 19, 2026 | 11:00 AM PT / 2:00 PM ET | 30 minutes
Serverless SQL warehouses start in seconds and scale on-demand, and they also make it easy for spend to grow unnoticed. Oversized warehouses, idle time before auto stop, too much concurrency scaling and dashboards that refresh on a timer all add to the DBU bill. Often nobody can say who is driving it.
In this webinar, Unravel's Head of AI, Prajakta Kalmegh, shows how to get serverless warehouse costs back under control: see where the money goes, tie it to the workloads and teams behind it, and right size without slowing down queries.
Walk away with practical steps that can cut warehouse spend by 25 to 35%. Register today.
Thursday, November 19, 2026
11:00 AM PT / 2:00 PM ET
30 minutes
Available on-demand after the event
Why serverless changes the cost equation: how warehouse spend behaves differently than on classic and pro warehouses
Where the money really goes: what we found in production SQL warehouses (shared hubs that never stop, monitoring tools that keep warehouses awake, dashboard refresh bursts, batch windows with idle cluster floors) and why each needs a different fix
Genie and AI on the warehouse: how natural language questions turn into many small, scattered queries, why one Genie backed warehouse spent a significant portion of its cost idle, and how to set things up before AI usage grows
One view of warehouse spend: query level cost, idle time, queuing and sizing signals in one place, so you know which change to make first
Platform engineering leaders, data engineers, FinOps and DataOps practitioners, analytics and BI leaders, and engineering managers running Databricks SQL warehouses who are looking to control serverless spend, see which teams and workloads drive it, and get ready for AI usage on the warehouse without slowing down queries.
A practical framework for getting serverless SQL warehouse spend under control: where the money goes, who is driving it, and which fix to make first. We will share what we found in production SQL warehouses, the patterns behind idle and oversized warehouses, and the changes that cut cost without hurting query performance.
Speaker
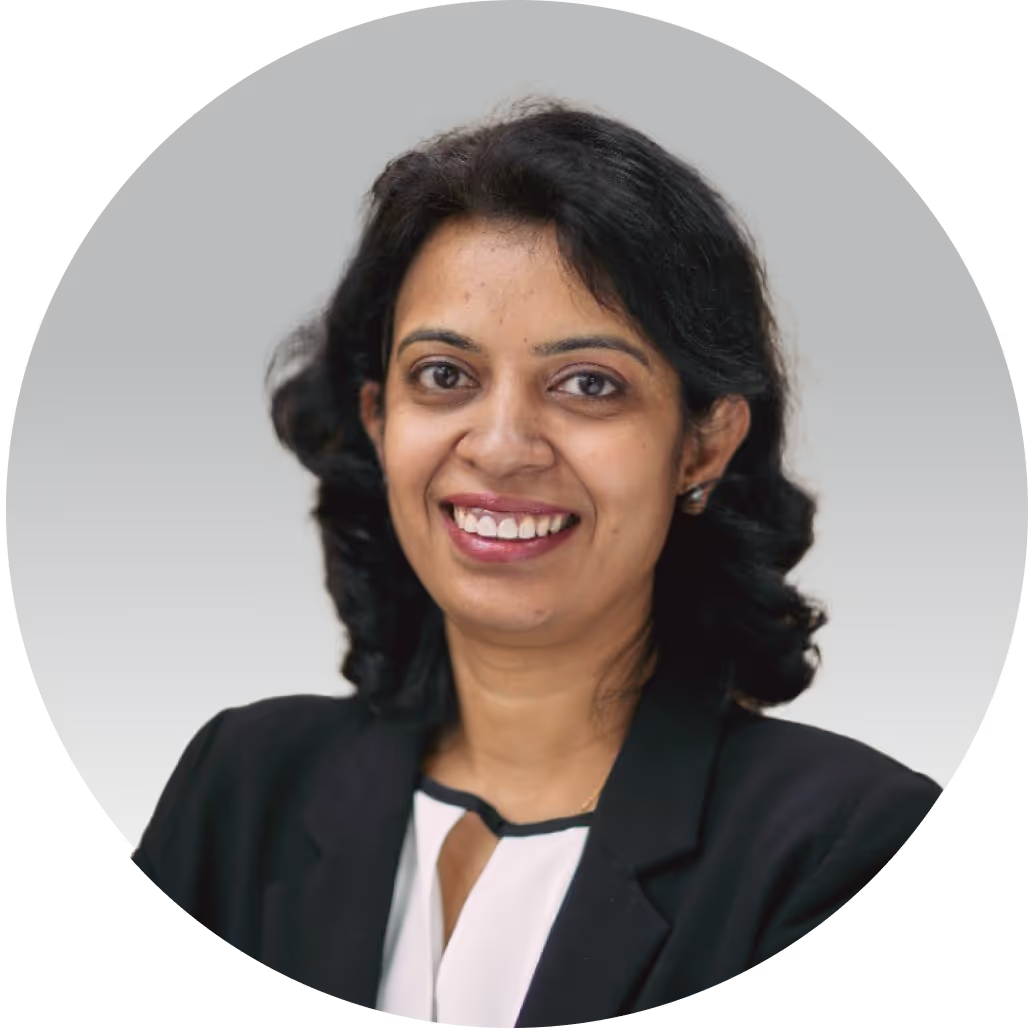
Prajakta Kalmegh
Prajakta has spent 21 years at the intersection of enterprise AI, cloud data infrastructure, and applied research. At Unravel, she leads the teams building the multi-agent systems that turn platform recommendations into validated, applied fixes.